Server
Windows and Linux servers that are patched, monitored and documented, so a bad update is an inconvenience rather than an outage.
This is usually when we get the call
- Patching is done manually, occasionally, and only when something breaks
- You find out a service was down when a user calls
- Nobody knows which server still runs that critical old application
- Disk space fills up and gets noticed at the worst possible moment
Patching on a schedule you approve
Unpatched servers are the most common way into a business, but patching everything immediately is how you cause the outage you were trying to prevent. Updates are staged and tested, with a rollback path, so security and stability are not a trade-off.
- Patch management with staged rollouts
- Rollback prepared before updates are applied
- Window agreed around your operating hours
Monitoring that reports before users complain
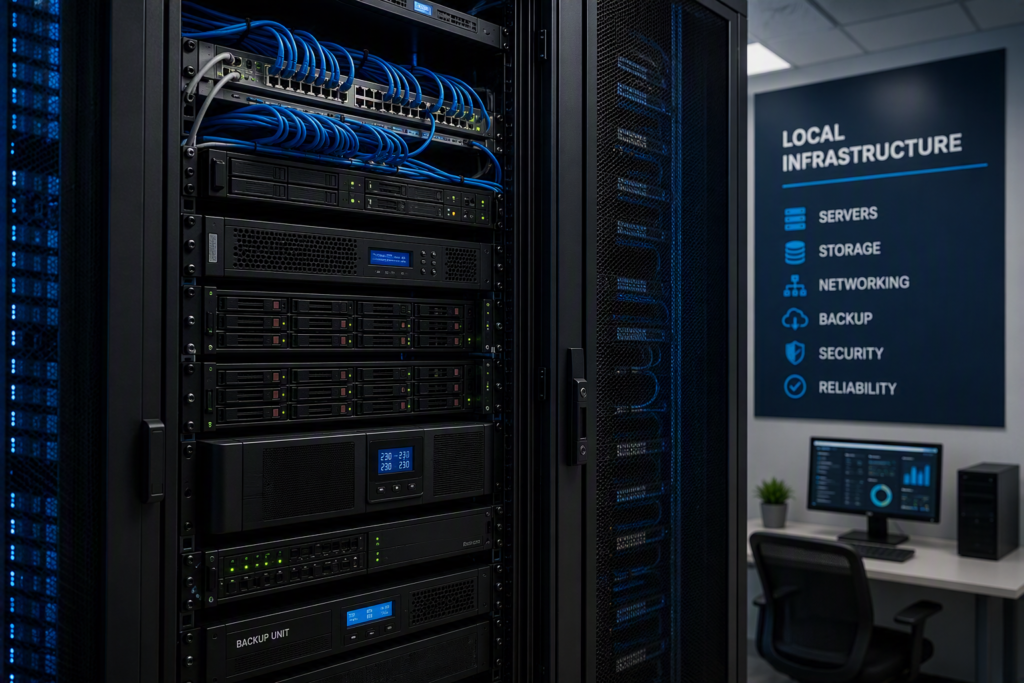
Disk space, failed services and certificate expiry all announce themselves in advance if somebody is watching. Capacity and health reporting turns those warnings into routine maintenance instead of emergency work.
- Monitoring, alerting and capacity reporting
- Backup, replication and tested restore procedures
- Migration and decommissioning of legacy servers
From first call to steady state
- 01
Inventory
Every server, role, dependency, and current patch level recorded.
Legacy systems that nothing depends on get flagged for decommission. - 02
Baseline
Monitoring, backup, and patch schedules set up and tested before steady-state begins.
We prove alerting works rather than assuming it does. - 03
Steady state
Staged patching with rollback, monitoring, and capacity reporting.
Patch windows agreed around your operating hours. - 04
Review
Capacity, incident, and patch reports reviewed with you on a regular cadence.
Decisions about replacement come from trend data, not a surprise failure.
Scope, spelled out
- Windows Server and Linux administration
- Active Directory, file, print and application servers
- Patch management with staged rollouts
- Monitoring, alerting and capacity reporting
- Backup, replication and tested restore procedures
- Migration and decommissioning of legacy servers
Before the first call
- An inventory of servers, roles, and who depends on each
- Admin access to the relevant systems and hypervisors
- Your patch window preferences
- A named contact for out-of-hours escalation decisions
Most delays in any engagement trace back to access, decisions, or content. Naming these up front is what keeps a project on schedule.
Straight answers
How quickly do you apply security patches?
Critical patches are prioritised, but staged rather than applied blindly, because an untested update can cause the outage it was meant to prevent. Each change has a rollback prepared and a window agreed around your operating hours.
What if a server fails at the weekend?
Monitoring and alerting run continuously, and response follows the same escalation rules as the rest of support. Recovery depends on the backup and replication design, which is why those are tested rather than assumed.
Do you support legacy systems?
Where they still run something the business depends on, yes, with the caveat that a vendor who has ended support limits what can be fixed. In those cases we document the risk and propose a migration path rather than pretending the risk is not there.
Can you take over mid-project from another provider?
Yes, and we do it in stages: inventory first, then monitoring and backup, then steady-state management. A handover plan reduces the chance of inheriting an undocumented environment with surprises in it.
Services that pair with this one
Ready to start?
Tell us what you are working with and we will tell you plainly what it takes. No obligation, no pressure.