Cloud LLM
Frontier models without the hardware bill, deployed inside your own tenancy so your data stays under your agreement.
This is usually when we get the call
- You want current models without a hardware capital purchase
- Procurement is slow and hardware would be obsolete before it is installed
- Usage needs to stay under your existing cloud agreement
- Spend needs a hard ceiling before anyone is allowed to use it
From first call to steady state
- 01
Selection
Models compared on quality, latency, and cost against your actual tasks.
Benchmarked on your workload, not on published leaderboards. - 02
Tenancy setup
Deployment inside your own cloud tenancy with residency and retention configured.
Keeps processing under the agreement you already hold. - 03
Integration
Wired into the tools your team already uses, with spend limits set.
Caps in place before rollout, not after the first surprise invoice. - 04
Operate
Usage monitored, models revisited as the field moves, prompts maintained.
Prompt and context management is ongoing work, not a one-off.
Frontier capability without buying GPUs
The strongest models change every few months, and hardware bought today will be outclassed before it is paid off. Running in the cloud lets you use current models, and swap them as the field moves, without a capital purchase.
- Model selection against cost, latency and quality
- Deployment inside your own cloud tenancy
- Data residency and retention configuration
Scope, spelled out
- Model selection against cost, latency and quality
- Deployment inside your own cloud tenancy
- Data residency and retention configuration
- Prompt and context management
- Usage monitoring and spend limits
- Integration with Teams, email and line-of-business apps
Your agreement, your boundary
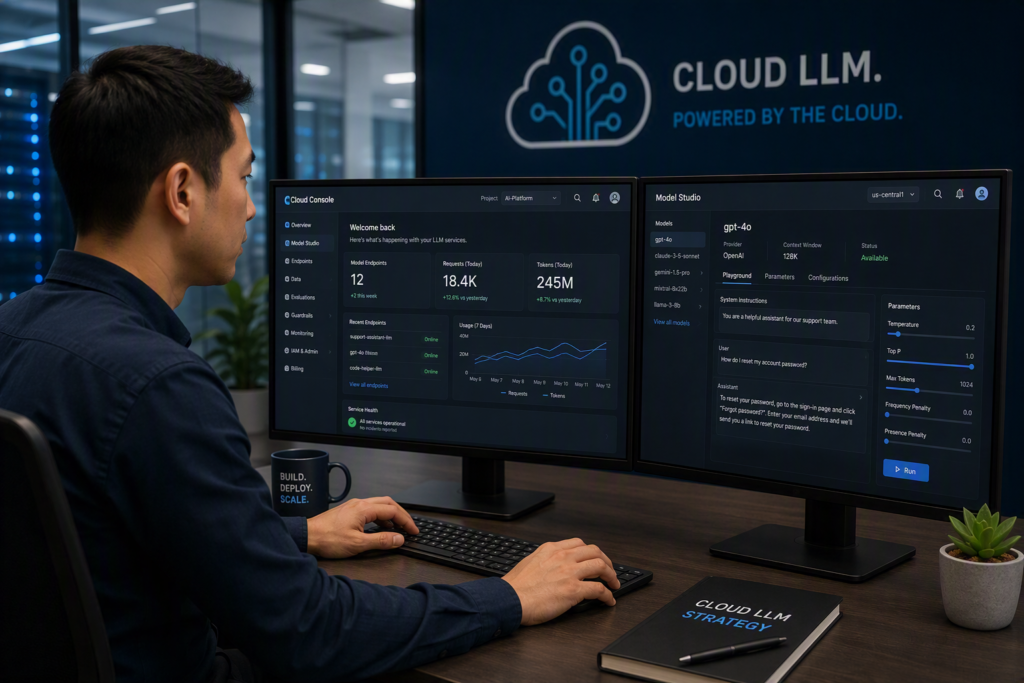
Consumer AI tools put your data under somebody else’s terms. Deploying inside your own tenancy keeps processing under the agreement you already have with your provider, with retention and residency set deliberately rather than by default.
- Usage monitoring and spend limits
- Prompt and context management
- Integration with Teams, email and line-of-business apps
Straight answers
How is this different from just using a public AI tool?
Placement and terms. Running inside your own tenancy keeps processing under the agreement you already hold with your cloud provider, with residency and retention configured deliberately. Public tools operate under their own terms.
Which model should we choose?
Whichever performs best on your actual tasks at acceptable cost and latency. We benchmark candidates against your workload rather than picking whichever is leading a public leaderboard this month.
How do we control spend?
Usage monitoring and hard spend limits are configured before rollout. A ceiling agreed in advance is the difference between a managed service and an incident.
What happens when a better model is released?
Swapping is a configuration change rather than a hardware purchase, which is much of the point. We revisit the choice periodically as part of ongoing operation, benchmarking candidates against your own tasks rather than adopting whatever leads a public leaderboard that week. The practical constraint is rarely the model itself: prompts, retrieval setup, and evaluation criteria all need adjusting when the underlying model changes, and that maintenance is part of the ongoing arrangement rather than a one-off migration.
Before the first call
- Your cloud tenancy details and budget ceiling
- The tasks you want the model to handle
- Data residency and retention requirements in writing
- The applications it needs to integrate with
Most delays in any engagement trace back to access, decisions, or content. Naming these up front is what keeps a project on schedule.
Services that pair with this one
Ready to start?
Tell us what you are working with and we will tell you plainly what it takes. No obligation, no pressure.